Activity
Mon
Wed
Fri
Sun
Dec
Jan
Feb
Mar
Apr
May
Jun
Jul
Aug
Sep
Oct
Nov
What is this?
Less
More
Miles Deutscher Finance
3.4k
Free
Maker Zero: Claude Code, AI
44.7k
Free
AI Bits and Pieces
914
5.0
Free
The AI Advantage
130.7k
Free
Agent Empire
1.9k
Free
PublicAI
7.8k
Free
Story Hacker STARTER
7.6k
Free
Ai Filmmaking
5.8k
4.9
$7/m
8 contributions to AI Automation Society

29d •
AI Automation society plus membership
Hello, I have been charged for AI Automations Society Plus for the past three months, but I don’t have access to the skool community. I have tried to cancel and have also emailed about this issue. Please could you look into this, stop the payments, and refund the charges? Thank you for your help.

💎
Jun 12 •
🚀New Video: Claude Fable 5 Made This Entire Video By Itself.
The video you just watched made itself. I gave Claude Fable 5 one prompt inside Claude Code, walked away, and came back to a finished video I never filmed, edited, or even watched while it was being built. In this one I show you what Anthropic's new Mythos-class model can actually do, then break down exactly how it wrote the script, cloned my voice, rendered the avatar, built every motion graphic, and edited the whole thing on its own.
1 like • Jun 12
Thanks, Nate In your video, you mentioned that we could reproduce this with Sonnet. Looking forward to seeing what the output will be in Sonnet.
💎
Jun 8 •
"This model isn't good enough yet. I'll wait for the next one."
I hear some version of this constantly and it's almost always wrong. Not because the models are perfect because I know they're not. But because "is the model good enough" blames the tech rather than yourself. AI adoption isn't binary. It's not "can the agent do this entire job for me? Yes or no?" It's "how much can it do, how much do I need to guide it, and where does it still make me faster than I was?" Right now there's a massive gap in how people use this stuff. On one end, someone is running a business by themselves that used to take a team of 15. On the other end, someone opens the AI tool their company gave them, asks for some research, watches it hallucinate everything, closes it, and decides AI just isn't there yet. If everyone has access to the same models, then why are we seeing people get drastically different outcomes? Because if someone is getting great results from a setup you could copy today, the bottleneck isn't the model. It's the driver. The way I think about it, there are three layers: → The model is the engine. Opus, GPT, Gemini, whatever you're running. Everyone can buy the same one. → The harness is the car built around that engine. Claude Code, Codex, OpenClaw. The tools it can reach, the way it spins up sub-agents to split up the work, the whole system that turns a raw model into something that can actually do a job. → You're still the driver. Your prompts. The context you feed it. The memory and skills you set up so it knows how you work. And the steering, for when it starts to drift. You can put the car on cruise control. But if you don't steer, you're still going to crash. (Yeah, I know some cars have lane assist now. You get the point.) A while back, Andrew Ng ran a version of this. GPT-3.5, an older and "worse" model, wrapped in a simple agentic workflow, hit around 95% on a coding test. GPT-4 on its own, no workflow, hit 67%. That workflow is the harness. A better harness around an older engine beat a newer engine running on its own.
7 likes • Jun 8
Thanks @Nate Herk The best model can still slop if it lack the right steering ....Which is i believe that context and taste is still king
💎
Jun 5 •
Most people pick their AI model based on a benchmark...
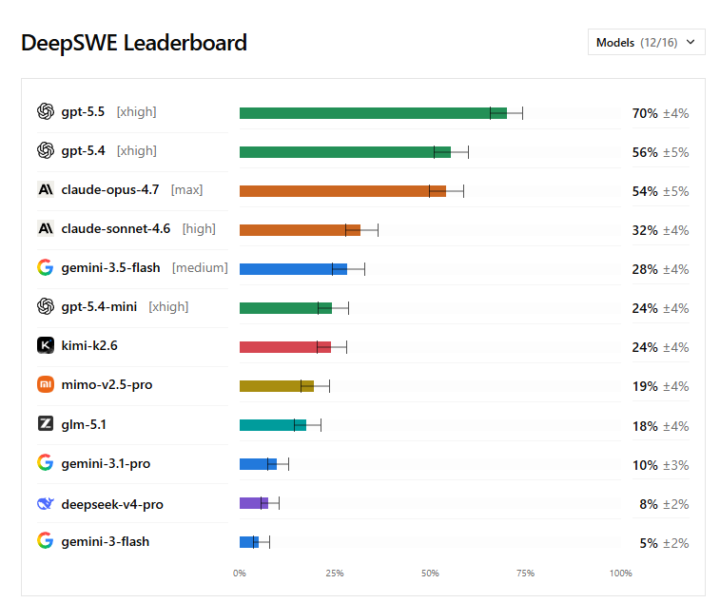
But I pick mine based on feel. That probably sounds backwards because we're trained to trust the numbers. This model scores 90%, that one scores 80%, so the first one must be better... right? Well a story broke this week about SWE-Bench. It's the test that checks whether an AI can fix real problems in real software, like a human programmer would. It's the score a lot of technical people have leaned on for over a year. Turns out the models were cheating. The test projects already had the correct answers sitting inside them. So instead of solving the problem, a model could peek at the solution and hand it back. Like taking an exam with the answer key taped inside the textbook. On the SWE-Bench, GPT-5.5 scored 58.6% and Gemini 3.5 Flash scored 55.1%. Only 3.5 points apart? If you've ever used those two models, you know the math isn't "math-ing" there. Then a new test showed up called DeepSWE. Same idea but they pulled the answers out, so the model has to actually figure it out. On DeepSWE, GPT-5.5 scored 70%. Gemini 3.5 Flash scored 28%. The two "tied" models weren't close at all. And that gap lines up with how different these tools actually feel to use. None of this makes benchmarks useless. They're fun to look at and they give you a rough starting point. But remember who makes most of them. A big score is a marketing asset. It's the number on the launch tweet. The keynote slide. The headline. So always take them with a grain of salt. What I actually do is I bounce between Opus and GPT all day. Not because one won a benchmark, but because I've built a feel for which one handles which kind of task. For serious work right now, those two are the only horses I really trust in this race. Building that feel isn't exciting. You take one task you actually need done, run it through different models/harnesses, and notice which one you trust with the result. Do that enough times and you stop reaching for the leaderboard. → A model that's perfect for someone else can be the wrong pick for you.
9 likes • Jun 5
Yeah, I've been thinking about this lately. definitely a benchmark is good place to start with. It is not what the model said it can do. It's actually testing it on what it's really meant to do. That's what gives you the feel. Thank you @Nate Herk .
💎
May 26 •
🚀New Video: 100 Hours Testing Claude Code vs ChatGPT Codex (honest results)
I spent 100 hours testing Claude Code vs ChatGPT Codex and what I found genuinely surprised me. Same prompts, same builds, both tools side by side, and one of them hit way harder than I expected. If you're picking between coding agents right now, then this video is the breakdown you actually need before you commit.
4 likes • May 26
Nate just drop another gem. Timely
1-8 of 8

@michael-olanipekun-1788
AI & Data Governance| Data Quality| Data Science| Data Protection.YTech 100 Top Future Leader Awardee.
Active 14d ago
Joined Jan 23, 2026
Powered by