Activity
Mon
Wed
Fri
Sun
Nov
Dec
Jan
Feb
Mar
Apr
May
Jun
Jul
Aug
Sep
Oct
What is this?
Less
More
AI & QA Accelerator
660
5.0
Free
3 contributions to AI & QA Accelerator
Mar 19 •
AI Coding Agents: Part 4 — Why the Same Model Gives Different Test Results
──────────────────────────────────────── ➤ Two Engineers. Same Model. Different Results. Engineer A asks the model to implement a feature. Gets back: clean, structured code. Follows existing patterns. Uses the right abstractions. Works on the first try. Engineer B does the same thing. Same model. Same task. Gets back: generic, messy code. Ignores existing patterns. Hardcodes values. Breaks immediately. ──────────────────────────────────────── 🚫 Most Engineers Blame the Model • "This model is bad at coding." • "It doesn’t understand our stack." • "I need a better model." That is usually the wrong diagnosis. Three other things determine the quality of the output far more than the model itself. ──────────────────────────────────────── ⚙️ Layer 1: The Harness You never talk to the model directly: Your Prompt » Harness / AI Agent » Model The harness decides what context gets sent to the model. Which files, what history, what project structure. A strong agentic tool sends relevant repo context, open files, and recent changes. That is why - same model. Different harness. Completely different output. ──────────────────────────────────────── 📁 Layer 2: Repo Quality AI agents amplify whatever already exists in your project. Clean architecture and consistent patterns? The agent tends to produce code that fits. Messy structure, inconsistent naming, no clear patterns? The agent produces more mess. Just faster. This is the hard truth: AI cannot rescue a poorly structured codebase. It usually makes the problems worse and accelerates the damage. The model is only as good as what it can see. When the repo has: • Clear structure • Consistent patterns • Good existing examples • Sensible abstractions …the agent pattern-matches against that and produces code that fits. When it sees nothing useful, it invents everything. That’s when quality becomes a lottery. ──────────────────────────────────────── 📝 Layer 3: The Task Spec “Implement the login feature” is not a real task specification. It’s a vague hint.

2 likes • Mar 20
Indeed a good read 💯
Dec '25 •
Happy Holidays! 🎄
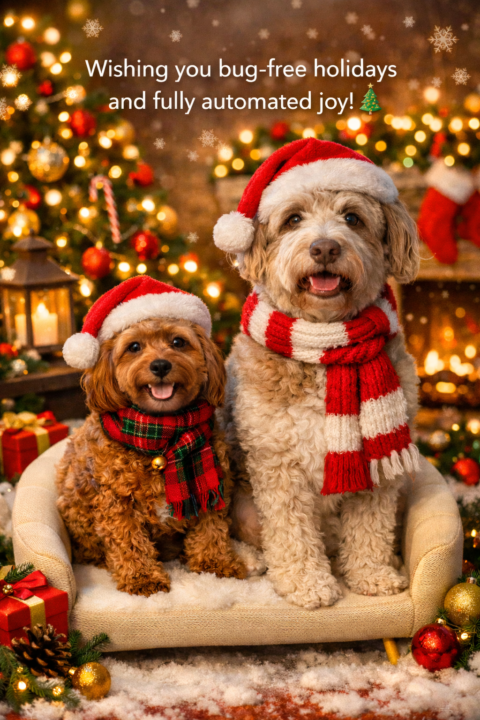
Happy Holidays, agent builders ! 🎄 Our furbabies wanted to send some festive cheer your way! Wishing you all a well-deserved break, time with loved ones, and a New Year full of career wins. Thank you for being such an amazing community! See you in 2026! 🚀
1 like • Dec '25
They are so cute and adorable 😍 Happy Holidays to everyone!
Sep '25 •
Stop the Web Slop: Pick your E2E Testing Framework
Make Your Life Simpler. Pick 𝗣𝗹𝗮𝘆𝘄𝗿𝗶𝗴𝗵𝘁. Here's why: ∙ No WebDriver management ∙ No browser compatibility issues ∙ Reporting is included ∙ AI can set it up in a few minutes without burning millions of tokens ──────────────────────────────────────── 𝗕𝗼𝗻𝘂𝘀: 𝗣𝗹𝗮𝘆𝘄𝗿𝗶𝗴𝗵𝘁 𝗖𝗟𝗜 Playwright CLI lets AI control the browser through the command line. It can scrape your pages, find locators, and use them to build reliable tests. Nothing else does this as well right now. ──────────────────────────────────────── Keep it simple. Pick Playwright.
1 like • Sep '25
Thanks for sharing this helpful item.
1-3 of 3
@jiper-reyes-6960
Manual QA with 4 years experience | Learning Automation (Python + Playwright)
Active 111d ago
Joined Aug 11, 2025
Powered by