Activity
Mon
Wed
Fri
Sun
Dec
Jan
Feb
Mar
Apr
May
Jun
Jul
Aug
Sep
Oct
Nov
What is this?
Less
More
AI Automation Society
484.1k
Free
6 contributions to AI Automation Society

11h •
First Website with the process
Hello guys, I stated the process and here is the website I build for a dentist clinic, i contact them and they interested to see the website so I send à WhatsApp message and waiting now. So happy now 😊😊 Can you give me feedback for this? I will appreciate ✌🏾 Https://cabinetlumiere.roschcorp.com

0 likes • 9h
@Lorenz Wieseke big YES to that it more value than remessage waiting for answer. I create a bonus for they WhatsApp business so tomorrow I can show then. Thanks ✌🏾
0 likes • 59m
@Dr. Stephen Buscema thanks bro Include that in process ✌🏾✅

💎
2d •
🚀New Video: I Tested Astra 6.2 vs. Fable 5.2 on 12 Real Use Cases
I put Fable 5.2 in Claude Code head-to-head with GPT-6.2 Astra in Codex across 12 real use cases, including web design, slide decks, a Canva painting, video editing, a 3D virtual summit, trip planning, financial models, and a browser game. Both ran on high effort with the exact same /goal prompt, and I tracked the cost, tokens, and runtime of every run. Fable won 7 to 5 on output, but it cost 7.2x more and ran almost 5x longer, even though both models are priced the same per token.
3 likes • 1d
Thank for the video, I’m very interested to try the skill for website and show you guys. Soon
💎
Oct '24 •
Welcome! Introduce yourself + share a career goal you have 🎉
Let's get to know each other! Comment below sharing where you are in the world, a career goal you have, and something you like to do for fun. 😊
1 like • 2d
@Christian Rivadeneira Thanks
0 likes • 2d
@Gal Miller Thank you for your encouragement. Today I created the first website for dentist clinic and tomorrow I will propose this website. 🙏🏾
💎
Oct '24 •
Please Read | Rules and Guidelines 📜
1) 🚫 No Business Promotions → NO “DM me for…” or "Comment 'Automation'" posts. 2) 🔗 No Linking Your Own Community/YouTube Videos 3) 🏷️ Title Specifically 4) 🔍 Search for Help First (searchbar) 5) 🙌 Stay Respectful 6) ❌ Enforced Clean‑Up Posts that break these rules will be removed without warning. If you ever have questions, feel free to ask. Let’s make this the best AI Automation community out there by sharing, collaborating, and learning together. 🚀
1 like • 2d
Very clear
💎
Apr 11 •
📚 Looking for a YouTube video resource?
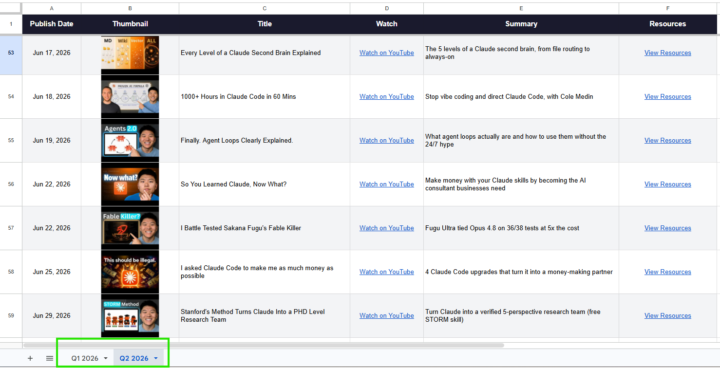
Hey everyone, I built a Google Sheet that has every video I've published in 2026 along with the links to all resources, tools, and files mentioned in each one. If you're ever looking for something I referenced in a video, start here: 📌 YouTube Video Database This will get updated as new videos drop. Bookmark it. Check the tabs at the bottom to make sure you're on the right sheet. - Nate
0 likes • 2d
Hi Nate, Can't the ressources for ths video The SIMPLEST Way To Make Money Online With Claude AI in 2026 https://www.youtube.com/watch?v=XSehihyKFqw posted on 16 Nov 2026
1-6 of 6

Active 58m ago
Joined Nov 17, 2026
Powered by